

Więcej o książce
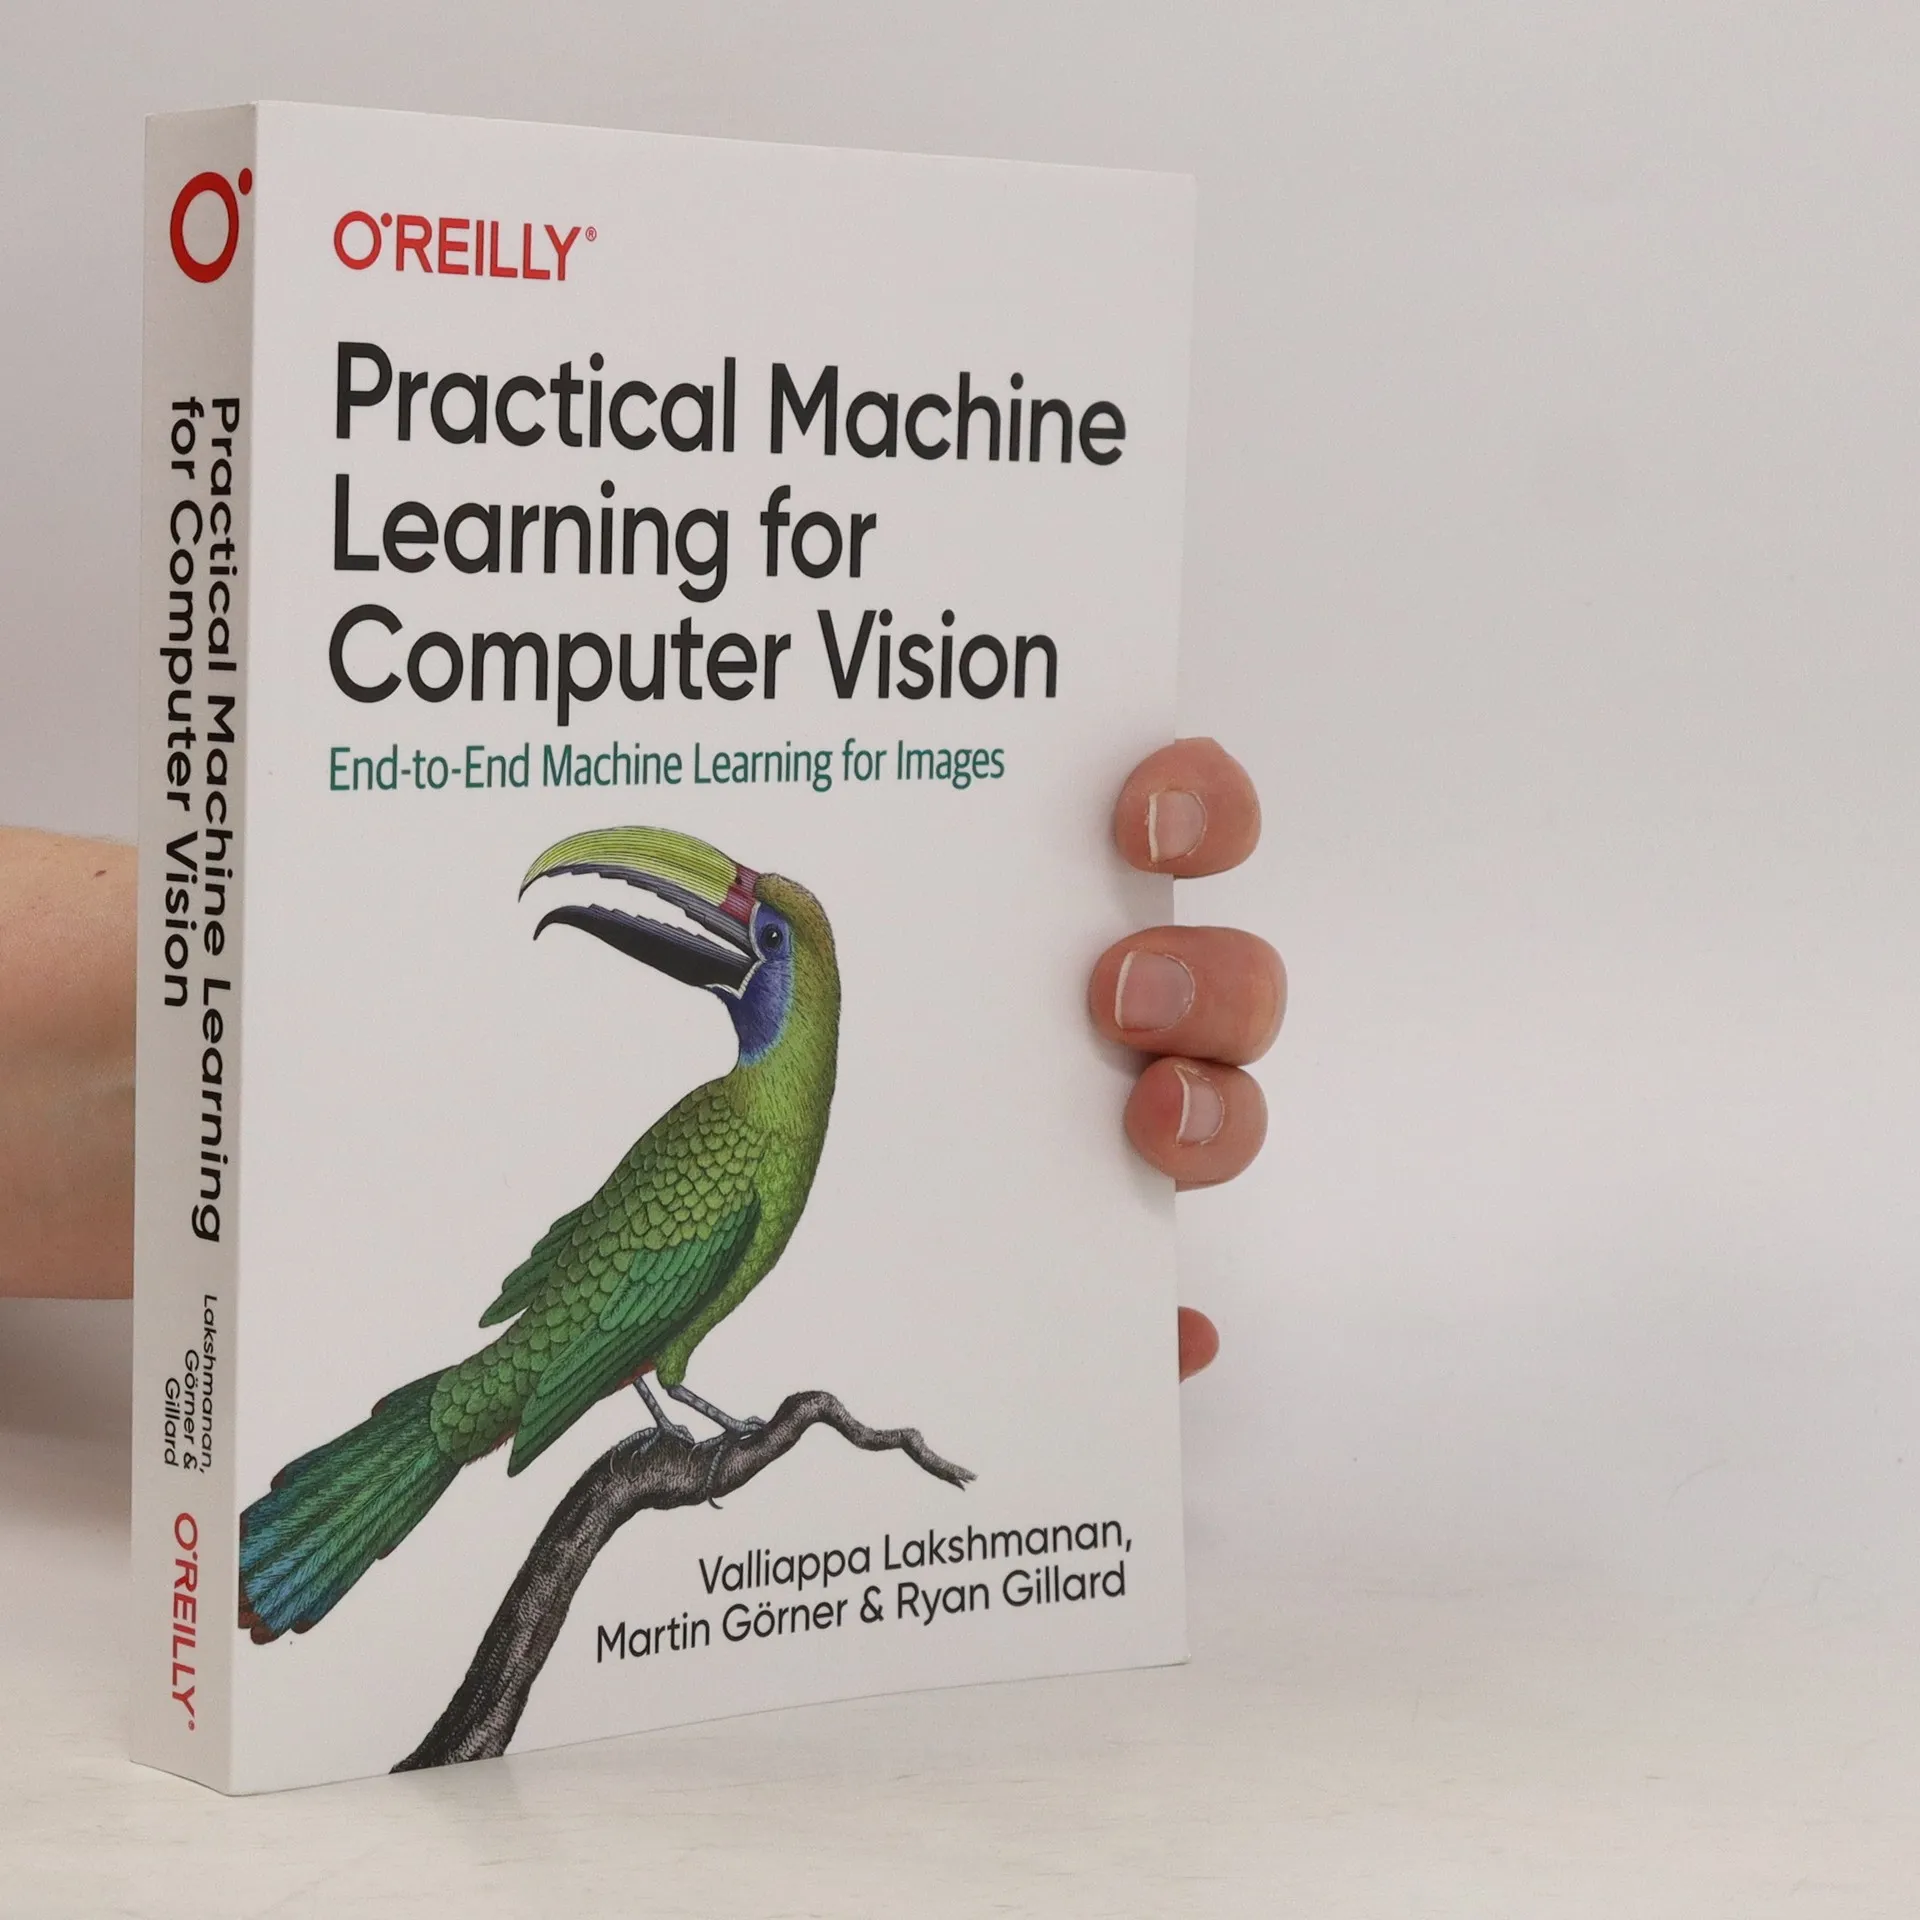
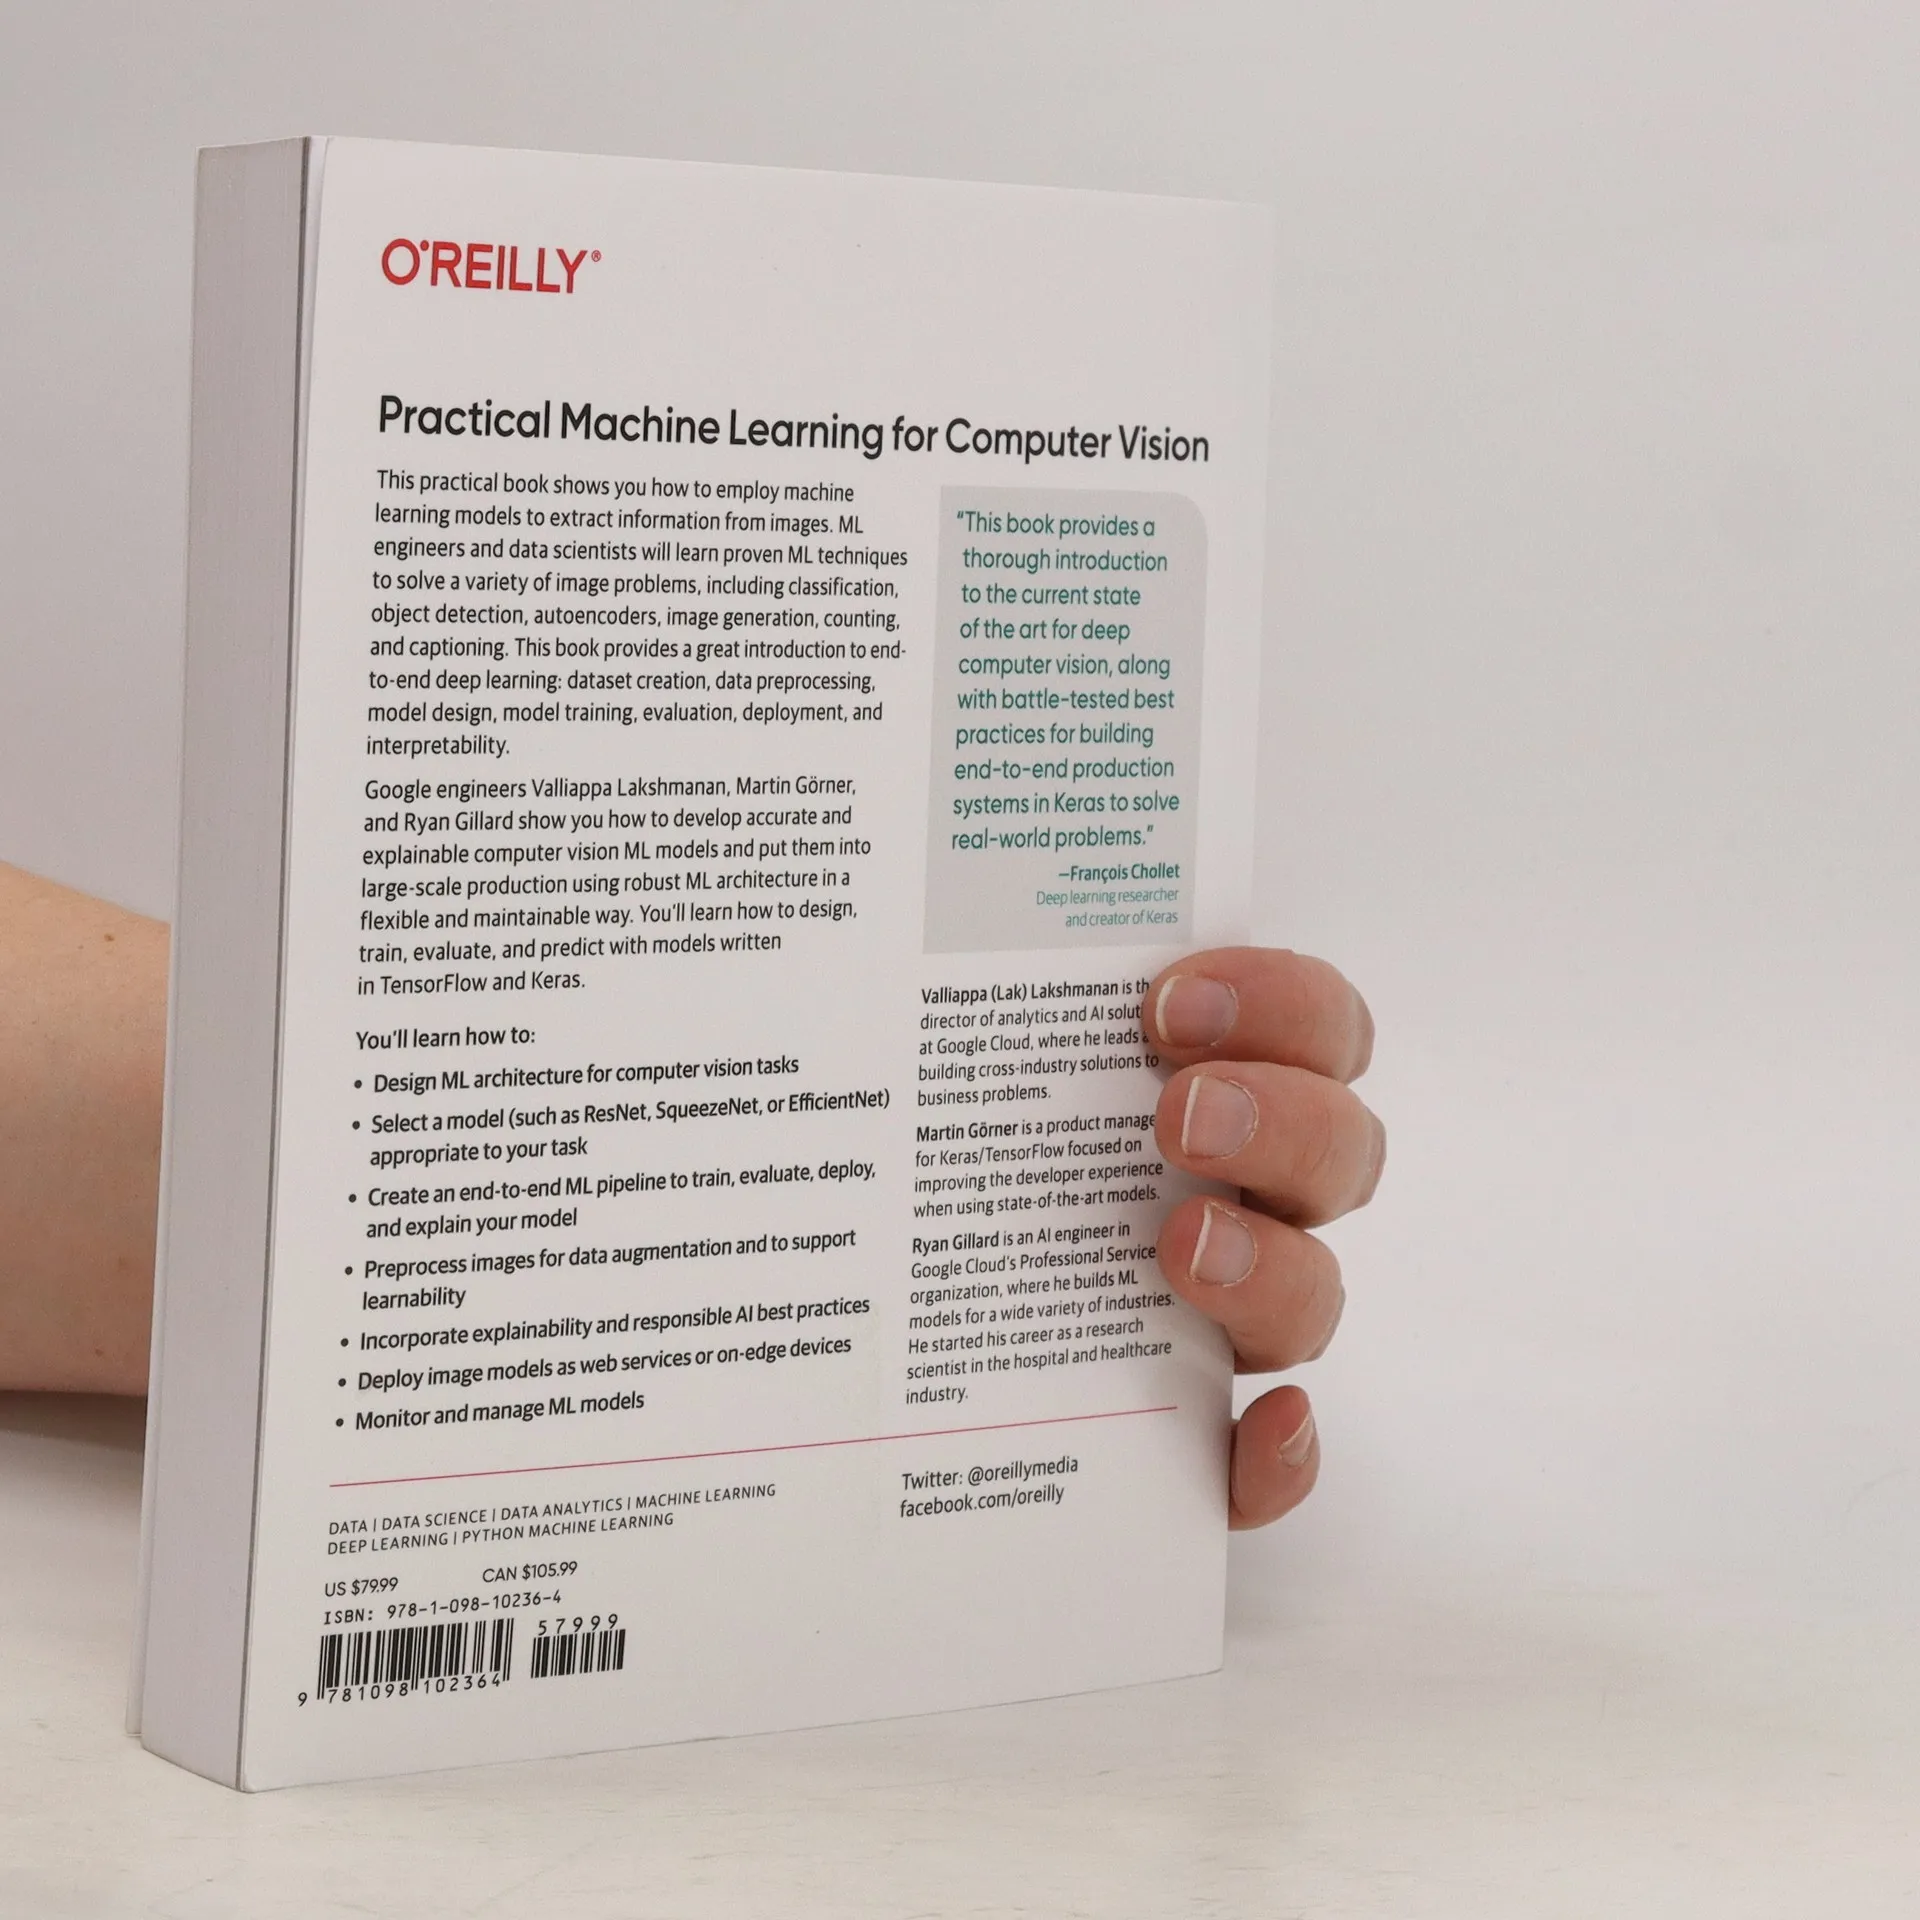
By using machine learning models to extract information from images, organizations today are making breakthroughs in healthcare, manufacturing, retail, and other industries. This practical book shows ML engineers and data scientists how to solve a variety of image problems including classification, object detection, autoencoders, image generation, counting, and captioning with proven ML techniques. Google engineers Valliappa Lakshmanan, Martin Garner, and Ryan Gillard show you how to develop accurate and explainable computer vision ML models and put them into large-scale production using robust ML architecture in a flexible and maintainable way. You'll learn how to design, train, evaluate, and predict with models written in TensorFlow/Keras. This book also covers best practices to improve the operationalization of the models using end-to-end ML pipelines. You'll learn how to: Design ML architecture for computer vision tasks Select a model (such as ResNet, SqueezeNet, or EfficientNet) appropriate to your task Create an end-to-end ML pipeline to train, evaluate, deploy, and explain your model Preprocess images for data augmentation and to support learnability Incorporate explainability and responsible AI best practices Deploy image models as web services or on edge devices Monitor and manage ML models
Zakup książki
Practical Machine Learning for Computer Vision, Valliappa Lakshmanan, Ryan Gillard, Martin Görner
- Język

- Rok wydania
- 2021
- Oprawa
- (miękka)
Metody płatności
Brakuje nam tutaj Twojej recenzji.
- Tytuł
- Practical Machine Learning for Computer Vision
- Język
- angielski
- Wydawca
- O'Reilly Media
- Rok wydania
- 2021
- Oprawa
- miękka
- Liczba stron
- 482
- ISBN10
- 1098102363
- ISBN13
- 9781098102364
- Seria
- Tagi
- Ocena
- 4,25 z 5
- Opis
- By using machine learning models to extract information from images, organizations today are making breakthroughs in healthcare, manufacturing, retail, and other industries. This practical book shows ML engineers and data scientists how to solve a variety of image problems including classification, object detection, autoencoders, image generation, counting, and captioning with proven ML techniques. Google engineers Valliappa Lakshmanan, Martin Garner, and Ryan Gillard show you how to develop accurate and explainable computer vision ML models and put them into large-scale production using robust ML architecture in a flexible and maintainable way. You'll learn how to design, train, evaluate, and predict with models written in TensorFlow/Keras. This book also covers best practices to improve the operationalization of the models using end-to-end ML pipelines. You'll learn how to: Design ML architecture for computer vision tasks Select a model (such as ResNet, SqueezeNet, or EfficientNet) appropriate to your task Create an end-to-end ML pipeline to train, evaluate, deploy, and explain your model Preprocess images for data augmentation and to support learnability Incorporate explainability and responsible AI best practices Deploy image models as web services or on edge devices Monitor and manage ML models